Non-Breaking Spaces and Other Invisible Characters Typographers Use
- Maria
- Typography
- 23 Oct, 2026
A price on your site wraps so that "$" sits at the end of one line and "1,299" starts the next. A long URL in a narrow sidebar overflows its container because there's nowhere for it to break. A test that compares formatted times fails even though both strings look identical in the error message. All three problems involve characters you can't see.
Unicode includes a whole family of invisible characters: spaces of different widths, spaces that don't break, break opportunities that take up no space, and joiners that control how neighboring characters connect. Typographers have used some of them for centuries. Others exist mainly for complex scripts and emoji. Used well, they give you precise control over spacing and line breaks. Used carelessly, they cause bugs that are hard to see and harder to search for.
This guide covers the invisible characters worth knowing, what each one does, how to use them in HTML and CSS, and how to find them when they cause trouble.
The Characters at a Glance
| Character | Code point | HTML | Width | Allows a break? |
|---|---|---|---|---|
| Space | U+0020 | (regular space) | Normal | Yes |
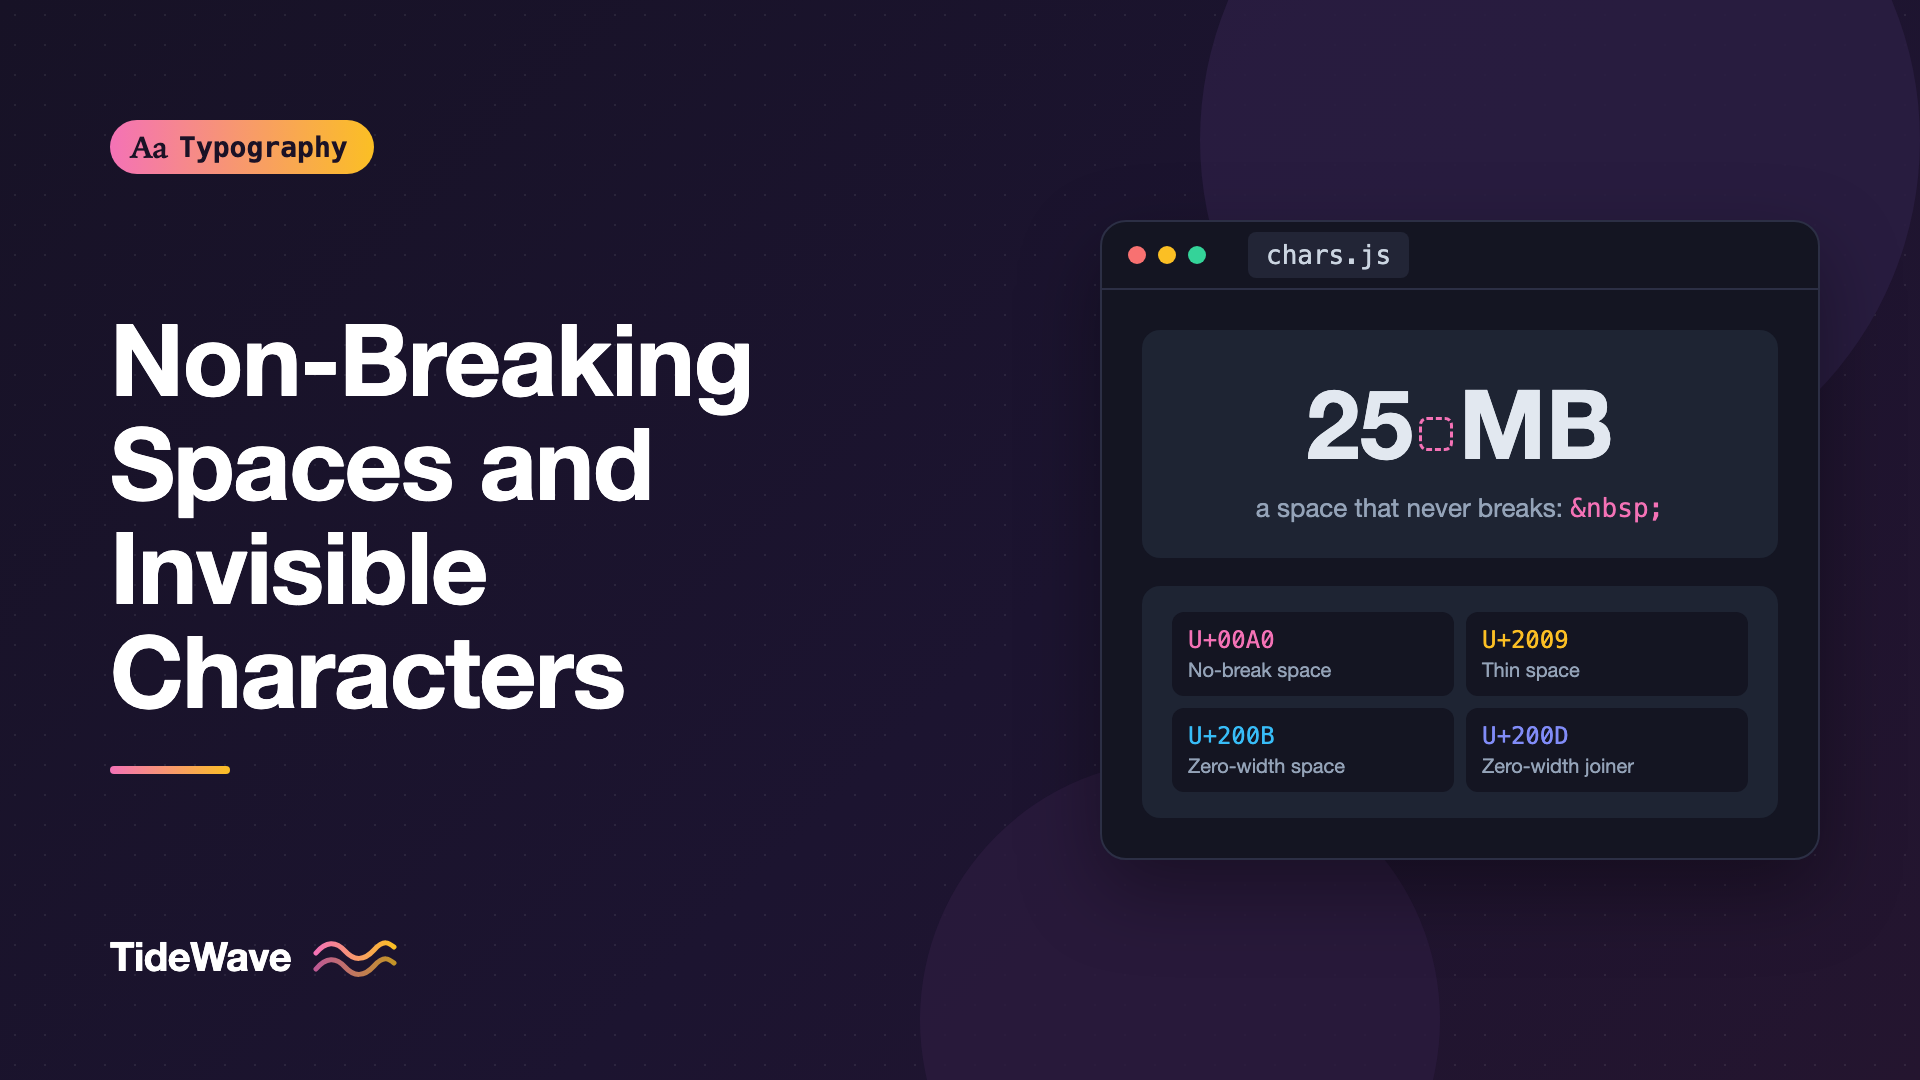
| No-break space | U+00A0 | | Normal | No |
| Narrow no-break space | U+202F |   | Narrow | No |
| En space | U+2002 |   | Half an em | Yes |
| Em space | U+2003 |   | One em | Yes |
| Thin space | U+2009 |   | Narrow | Yes |
| Hair space | U+200A |   | Very narrow | Yes |
| Figure space | U+2007 |   | One digit | No |
| Zero-width space | U+200B | ​ | None | Yes |
| Word joiner | U+2060 | ⁠ | None | No |
| Soft hyphen | U+00AD | ­ | None (hyphen at break) | Yes, with hyphen |
| Zero-width joiner | U+200D | ‍ | None | No |
| Zero-width non-joiner | U+200C | ‌ | None | No |
The exact widths of the fixed spaces depend on the font. A thin space is often around a fifth or sixth of an em, and a hair space is thinner still.
The Non-Breaking Space
The no-break space, usually called a non-breaking space, looks exactly like a normal space but prevents a line break at that position. It's the invisible character you'll use most.
Use it to keep things together that would look wrong split across lines:
- Numbers and their units:
10 km,250 ms,16 px - Currency and amounts when the symbol is separated by a space, such as
1 299 €in some locales - Names with initials or titles:
Dr. Chen,J. R. R. Tolkien - Short words that shouldn't end a line, like
Section 4orpage 12 - The last two words of a headline, to avoid a single word on the final line
<p>The upload limit is 25 MB per file.</p>
<p>See Figure 3 for the full results.</p>
Non-Breaking Spaces Don't Collapse
HTML collapses runs of regular spaces into one. Non-breaking spaces don't collapse, so several in a row create a wider gap. This is why became a notorious layout hack for indentation and spacing in old HTML. Use CSS margins and padding for layout instead. Reserve non-breaking spaces for keeping words together.
Headlines and text-wrap
The last-two-words trick for headings is less necessary now that text-wrap: balance and text-wrap: pretty exist. Those properties let the browser avoid short last lines automatically, at every width. Non-breaking spaces can even fight with balance by removing break options. The widows and orphans guide compares the approaches.
The Narrow No-Break Space
The narrow no-break space (U+202F) is a thinner non-breaking space. French typography uses it before certain punctuation marks, such as before ? ! ; : and inside guillemets, where a full space looks too wide:
<p lang="fr">Vraiment ? « Bonjour »</p>
It's also used as a thousands separator in some locales, where 1 000 000 needs spaces that never break.
A Surprise from Intl
The narrow no-break space can show up in output you didn't write. Some versions of the Unicode CLDR locale data, used by Intl in browsers and Node.js, put U+202F between the time and "AM" or "PM" in English time formatting. Depending on the runtime version, this code might produce either a regular space or a narrow no-break space:
const time = new Date("2026-10-23T09:30:00").toLocaleTimeString("en-US", {
  hour: "numeric",
  minute: "2-digit",
});

console.log(JSON.stringify(time)); // "9:30 AM" (the space may be U+202F)
console.log([...time].map((c) => c.codePointAt(0).toString(16)));
If you compare formatted strings in tests or parse them on a server, don't assume a regular space. Normalize first, or compare against the output of the same formatter.
Fixed-Width Spaces
Typographers have long used spaces of specific widths for fine adjustments. Unicode includes them:
- En space and em space, half an em and a full em wide. Useful for deliberate gaps in plain-text contexts, though CSS margins are usually better in HTML.
- Thin space, used around em dashes by typographers who want a little air, between digits in some number formats, and between a number and a unit in some style guides.
- Hair space, the thinnest, for optical adjustments like separating a closing quote from an adjacent mark.
- Figure space, exactly the width of a digit in fonts with tabular figures, for aligning numbers in plain text.
<p>
The fix — finally — shipped on Monday.
</p>
<p>Population: 8 336 817</p>
All of these except the figure space allow line breaks. If you want a thin gap that also doesn't break, use the narrow no-break space. The dashes guide covers spacing around dashes.
Zero-Width Characters
Some characters take up no space at all. They exist only to control line breaking or how adjacent characters behave.
Zero-Width Space and wbr
The zero-width space (U+200B) marks a place where a line may break, without adding any visible space or hyphen. It's useful for long strings without natural break points, like URLs, file paths, and long compound identifiers:
<p>
Config file: /usr/local/etc/​nginx/​sites-available/​default
</p>
HTML has an element for the same purpose, wbr, which is often cleaner in markup:
<p>Endpoint: api.example.com/<wbr />v2/<wbr />organizations/<wbr />members</p>
The difference matters when people copy text. A zero-width space is a real character, so it comes along when someone copies the path, and pasting it into a terminal or config file can cause a confusing error. The wbr element isn't a character, so copied text stays clean. Prefer wbr in HTML.
For user-generated content where you can't insert break points, use CSS instead:
.sidebar a,
.file-path {
  overflow-wrap: anywhere;
}
overflow-wrap: anywhere lets the browser break long strings anywhere when they'd otherwise overflow, without touching the content.
Word Joiner
The word joiner (U+2060) is the zero-width opposite of the zero-width space: it prevents a break between the characters on either side, without adding space. It's useful for keeping a symbol attached to a word where the browser might otherwise allow a break, such as a slash or a dash.
<p>Supports read⁠/⁠write access.</p>
The older character for this job, U+FEFF, is now used almost exclusively as a byte order mark at the start of files. Use U+2060 for word joining.
Soft Hyphen
The soft hyphen (­) is invisible unless the browser breaks the line at that point, in which case it shows a hyphen. It lets you suggest hyphenation points for specific words, which is useful for long words in narrow headings or languages without browser hyphenation support:
<h2>Inter­nationali­zation guide</h2>
The hyphenation guide covers soft hyphens alongside hyphens: auto.
Joiners for Scripts and Emoji
Zero-Width Joiner
The zero-width joiner (ZWJ, U+200D) tells the rendering engine to connect characters that would otherwise display separately. It has two main uses:
- Emoji sequences. Many emoji are built from several code points joined with ZWJ. A family emoji, for example, can be several person emoji joined into one glyph. If the font doesn't support the sequence, the parts display side by side.
- Complex scripts. In scripts like Arabic and several Indic scripts, ZWJ requests a joining or conjunct form where the default rendering would show something else.
Zero-Width Non-Joiner
The zero-width non-joiner (ZWNJ, U+200C) does the opposite: it prevents characters from joining. It's essential in Persian, where certain words must show a letter in its unjoined form even though the next letter would normally connect to it. It's also used in some Indic scripts and occasionally to break an unwanted ligature in Latin text.
These characters are part of correct spelling in those languages. Never strip them from user content in a blanket cleanup, or you'll break text in those scripts and break emoji.
Inserting Invisible Characters with CSS
You can add invisible characters through generated content using CSS escapes:
.price::before {
  content: "$\00a0";
}

.unit::before {
  content: "\202f";
}
The escape is a backslash followed by the hexadecimal code point. If the next character could be read as part of the hex number, end the escape with a space or use the full six digits.
In JavaScript strings, use \u escapes, which make invisible characters visible in your source code:
const NBSP = " ";
const label = `25${NBSP}MB`;
Writing invisible characters directly in source code is risky. They're impossible to see in review, and editors may convert them to regular spaces or leave them in when you meant to remove them. Escapes and entities make your intent explicit.
Finding Invisible Characters
Invisible characters cause real bugs: failed string comparisons, broken search, mysterious validation errors in form fields, and copied commands that don't run. Here's how to find them.
In Your Editor
VS Code highlights many unusual invisible characters by default, through its Unicode highlighting settings. Search with a regular expression to find specific ones:
grep -rnP "[\x{00A0}\x{200B}-\x{200D}\x{2060}\x{FEFF}]" src/content
That command needs a grep with Perl-compatible regex support, like GNU grep. On macOS, rg (ripgrep) handles the same pattern.
In JavaScript
To normalize user input, replace invisible spacing characters with regular spaces and remove zero-width break characters, while leaving joiners alone:
function normalizeSpaces(input) {
return input
.replace(/[ - ]/g, " ")
.replace(/[]/g, "")
.trim();
}
normalizeSpaces("25 MB"); // "25 MB"
Use this for search, comparison, and identifiers like usernames and email addresses. Don't apply it to content you display, where non-breaking spaces are often intentional, and don't remove ZWJ or ZWNJ from text.
In DevTools
In the Elements panel, non-breaking spaces in text nodes are displayed as , which makes them easy to spot. For other characters, copy the text into the console and inspect code points:
[..."Price: $12"].map((c) => c.codePointAt(0).toString(16).padStart(4, "0"));
Common Mistakes
- Using
for layout, stacking several to create indents or gaps that should be margins or padding. - Gluing too many words together, which can make text overflow narrow containers.
- Using zero-width spaces in copyable text like file paths and commands, where
wbrwould keep the copied text clean. - Stripping all zero-width characters from user input, which breaks emoji sequences and correct spelling in Persian and other scripts.
- Typing invisible characters directly into source code instead of using escapes or entities.
- Assuming
Intloutput uses regular spaces, which causes test failures when it returns U+202F or U+00A0. - Forgetting that non-breaking spaces affect search and matching, so "25 MB" in a search box doesn't match
25 MBin content unless you normalize both.
Conclusion
Invisible characters give you control that regular spaces can't. Non-breaking spaces keep numbers with their units and names with their initials. Thin and hair spaces handle fine spacing. Zero-width spaces and wbr create break points in long strings, the word joiner prevents unwanted breaks, and the joiners make emoji and complex scripts render correctly.
Use them deliberately, write them as entities or escapes so they're visible in your source, and normalize them when comparing or searching text. A quick search of your codebase for stray U+00A0 and U+200B is a good way to find the bugs they've already caused.